Is Rokoko Vision generative AI? How markerless motion capture actually works (2026 guide)
The short answer
No, Rokoko Vision is not generative AI. It is markerless motion capture that uses AI to estimate and reconstruct the performance captured in your video, rather than generate a new performance. The result is editable 3D animation of the person you filmed. Our Text-to-Motion feature is the generative one: it creates new animation from a written prompt.
- Not generative AI: Rokoko Vision reconstructs the motion in your video. It does not create a new performance.
- Markerless: no suit, sensors or reflective markers. You record yourself with any camera or use any video file.
- Editable 3D data: you get a skeleton animation (FBX or BVH) to clean up, retarget and reuse, not a finished video.
- Preserves your performance: the acting and timing in your footage carry through to the animation.
- Why does it matter? Some creators and studios specifically want to avoid generative AI in their workflows, so understanding what the tools they use actually do matters.
What is markerless motion capture?
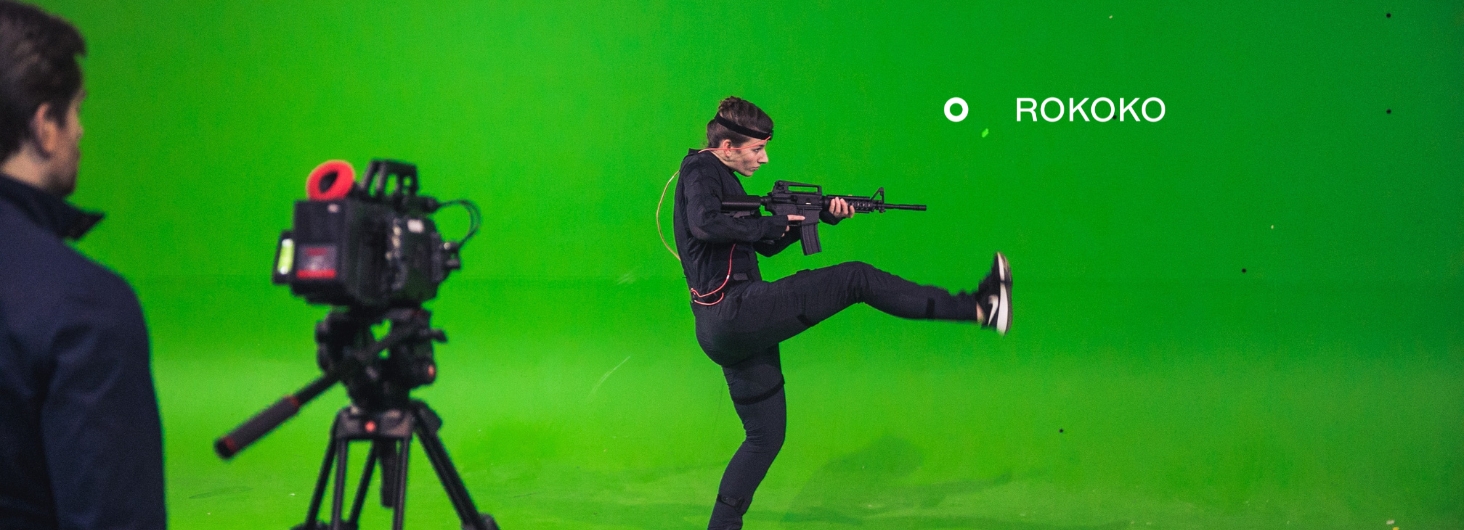
Markerless motion capture records human movement without suits, sensors or reflective markers. The performer is filmed, and software works out the position of the body from the images. Sensor-based systems such as the Rokoko Smartsuit Pro work the other way: inertial sensors on the body capture the movement directly.
How does Rokoko Vision work?
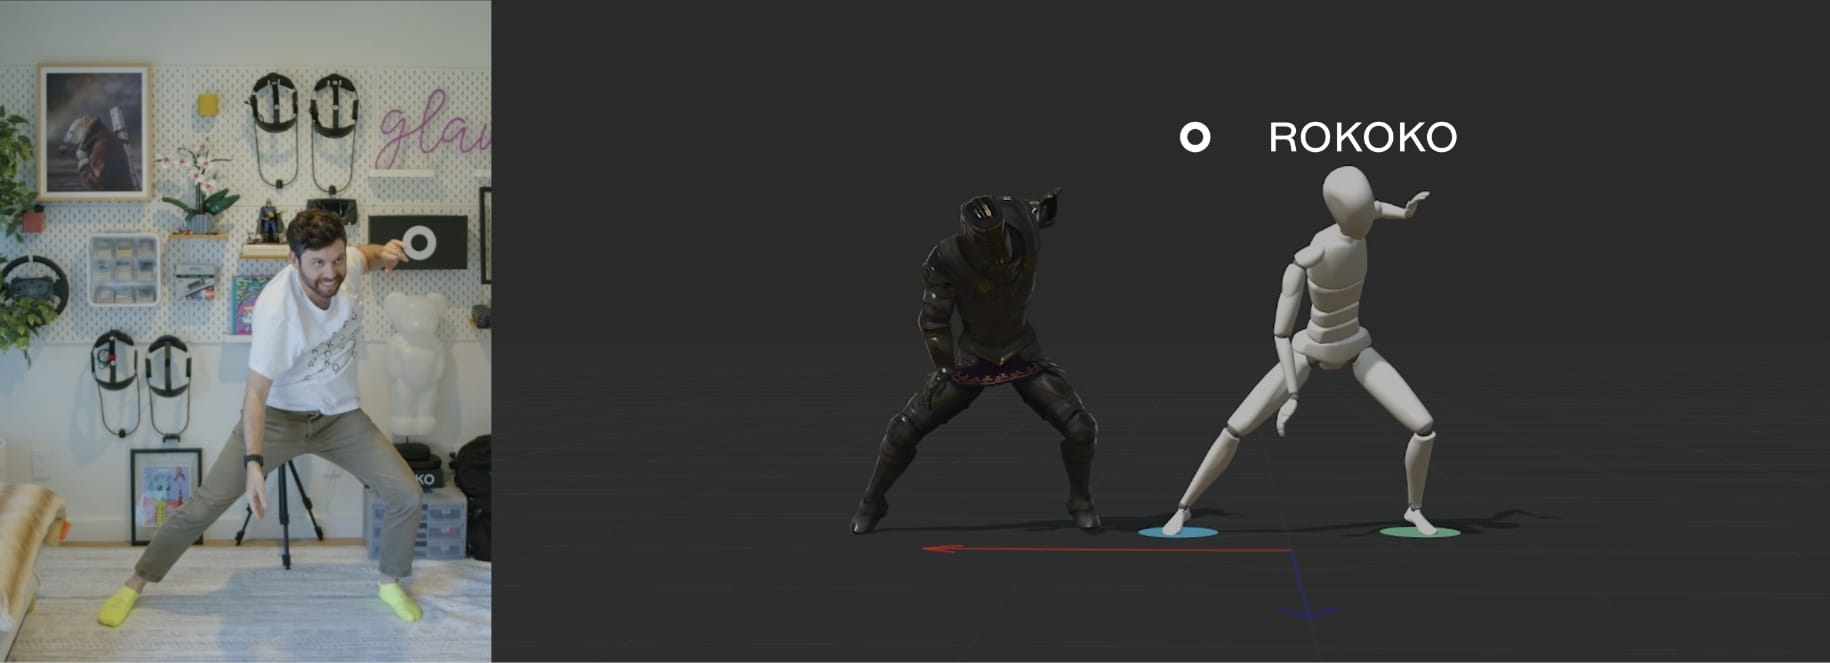
Rokoko Vision analyses your video, estimates the performer's skeleton in 3D, and turns the result into an animation you can edit and export. Video goes in, motion data comes out.
The workflow, step by step
- Record or choose a video. One performer should be clearly visible with the full body in frame.
- Upload it to Rokoko Create. Vision 3.0 runs on a monocular AI solver we rebuilt from the ground up, with faster cloud processing.
- Edit in Rokoko Studio. Preview the result, clean it up and retarget it to your character.
- Export. Download as FBX or BVH for Blender, Unreal Engine, Unity, Maya, Cinema 4D, Houdini, MotionBuilder or iClone.
What does the solver rely on?
A single camera sees a flat image, so the solver has to estimate depth and orientation to rebuild the pose in 3D. Our filming guidance is built around what it needs:
- Clear outlines. Vision 3.0 relies on clear outlines to map joint rotations.
- Visible joints. Baggy clothes hide the hips, knees and elbows, and dark clothing makes joint depth and orientation harder to calculate.
- A skeleton you can retarget. The result works with skeletons such as UE5 Manny, HIK and Mixamo.
- Less noise. Vision 3.0 drastically reduces joint noise and micro-jitter, which saves cleanup time.
That is why we recommend a stationary camera on a tripod at chest height, the full body in frame, form-fitting clothes and even lighting.
Is Rokoko Vision generative AI?
No. Generative AI produces new content from a prompt. Rokoko Vision uses AI to estimate and reconstruct the performance in your video. We draw the same line in our Vision 3.0 announcement: we capture motion from video, and we generate new performances from text. In practice, that gives you three things:
- Control: you decide the acting, timing and framing on set.
- Editable 3D data: the output is a skeleton animation you can edit, view from any angle and reuse across scenes. Generative video tools output a rendered video.
- Your own performance: the movement comes from the person you filmed.
How does Rokoko Vision compare with Text-to-Motion and mocap suits?
Rokoko Vision reconstructs a real performance from video, Rokoko Text-to-Motion generates new animation from a written prompt, and sensor-based suits capture motion directly from the body. All three give you editable 3D animation, and only Text-to-Motion is generative AI.
What are the limits of markerless mocap with Rokoko Vision?
Single-camera markerless mocap works best when the performer is clearly visible. Knowing the limits helps you film footage that captures cleanly.
- One camera, one view. A single camera has to estimate depth. When a limb is hidden, Vision has less visual information to work from, so its estimate can be less accurate. You can clean it up in Rokoko Studio.
- One performer at a time. Our Vision page notes there are "no convincing AI motion capture tools that can capture more than 1 performer" in one recording.
- Not real time. Our Vision page explains that AI motion capture needs post-processing to generate the animation file.
- No finger tracking (yet). Vision 3.0 launched without finger tracking. For detailed hands, see Rokoko Smartgloves.
- Footage quality matters. Even lighting and the full body in frame, head to feet, improve the result.
Who should use Rokoko Vision?
Choose Rokoko Vision if:
- You want to capture a specific performance with your own acting and timing
- You have no suit or budget for hardware and want to start with a camera
- You need editable animation for a game, short film or previs
- You are just getting started with motion capture and 3D animation
- Your shots feature one performer who stays fully in frame
Choose a sensor-based suit if:
- You need real-time feedback while capturing
- More consistent or higher-fidelity motion capture
- Occlusion, tight spaces or multiple takes make camera tracking unreliable
- You need fingers and face captured together with the body
What about our Text-to-Motion feature?
Text-to-Motion is a separate feature in Rokoko Create. Unlike Vision, it is generative AI: you type a short prompt, such as "A character walks slowly", and it generates a new full-body 3D skeleton animation, with no camera, suit or performer. You can crop, smooth and loop the result in Rokoko Studio.
Final thoughts
AI in motion capture does not always mean generative AI. Rokoko Vision uses AI to estimate and reconstruct a real performance from ordinary video, and the result is editable 3D motion data that preserves what you filmed.
Want to see how it works on your own footage? Try Rokoko Vision in Rokoko Create, or book a demo and we will walk you through the right setup for your project.